Skip to content

For 국내 ai 모델 학습, 추론 플랫폼 및 mlops 엔지니어

KT Cloud · NHN Cloud 멀티노드 H100 환경의 NCCL 타임아웃 원인 분리

단일 노드의 InfiniBand/RoCE 통신 장애, VPC 보안 그룹 포트 차단, 또는 Xid 79 하드웨어 폴트로 인한 전체 랭크 멈춤을 즉시 판별합니다.

Free 30-day Team evaluation. No card or automatic subscription. Work email verification required.

Live diagnosis, no signup

국내 멀티노드 H100 NCCL 타임아웃 로그 재현

Upload your log file. Review the selected evidence and masking, then run diagnosis. Keep the original log for any follow-up questions.

Before uploading, review cloud data handling and local options.

training_logs.txt
No log to hand? Try one:

Upload your log file. Large files are processed in your browser. Only selected evidence is submitted when you run diagnosis.

3 free cloud diagnoses per day

Try Denpex for 30 days. FREE.

No credit card. No automatic subscription. See whether Denpex helps with an incident you already understand.

Start your free 30-day Team evaluation

Up to 50 diagnoses a day for 30 days. Verify your work email to activate an eligible company evaluation, then replay a resolved incident and compare the evidence and next steps with your team's confirmed cause.

Use your company email, for example alex@yourcompany.com.

Who qualifies?

Company email domains activate the free 30-day Team evaluation (up to 50 diagnoses a day) after an email and domain check, whatever mail provider you use. If we cannot verify your domain automatically, support reviews it: write to support@denpex.com. Free local diagnosis in the editor extension needs no account.

Using a personal email (Gmail, Outlook, Naver, QQ) or solo cluster? Create a free $0 account (no work email required) to save 7-day history and unlock AI fallback, or send a cluster crash log for a live walkthrough.

What a useful evaluation should establish

정상 노드를 불필요하게 재기동하지 않고 문제 노드와 정확한 네트워크 설정 오류만 분리 보고합니다.

Use Denpex alongside your existing telemetry tools to investigate submitted incident evidence. With monitoring configured on a supported plan, detected failures can trigger alerts and an automatic diagnosis from the captured evidence.

Inside Denpex

See the evidence, not just the claim

Follow the causal chain, inspect the quoted evidence and prepare the next handoff. These actual product captures use founder-account examples and the VS Code extension, with the source identified under each image. Open a capture to inspect it at full size.

Follow the failure through the cascade
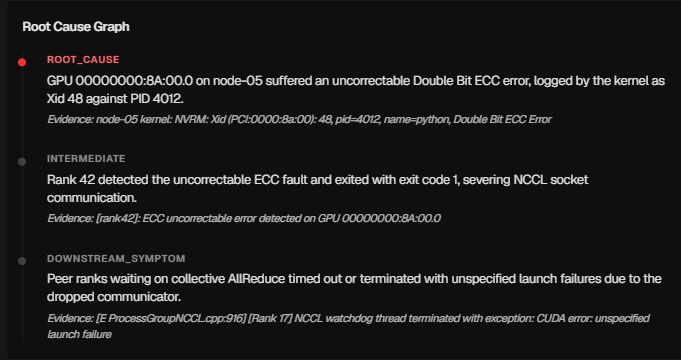
Denpex founder-account example: a causal graph connects an Xid 48 ECC event to a rank exit and downstream collective failures, with quoted evidence for each stage.
Live founder-account capture from the bundled NCCL/ECC example. Follow the hardware event, rank exit and downstream symptoms with a supporting log quote at each stage.Inspect original image

Prepare the hardware escalation

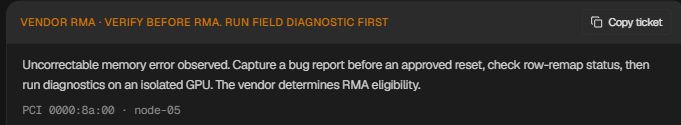
Denpex hardware handoff summary asks the operator to capture diagnostic evidence and verify RMA eligibility with the vendor.
Actual hardware handoff summary from the same founder-account example. Capture diagnostic evidence before an approved reset, then confirm RMA eligibility with the vendor.Inspect original image

Ask for the evidence that is missing

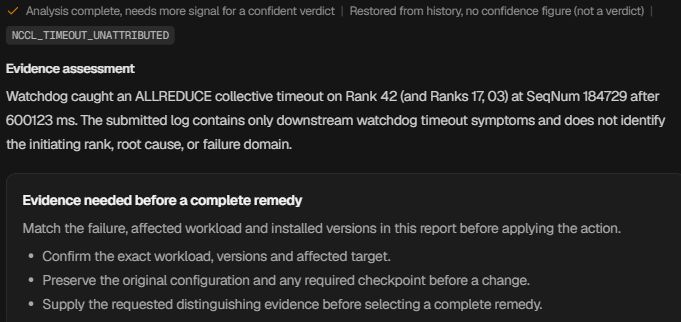
Denpex historical example says a collective timeout does not establish the initiating rank, cause or failure domain and requests distinguishing evidence before a remedy.
Founder-account example restored from history. The original timeout remains unattributed, and the UI keeps the missing-evidence assessment visible.Inspect original image

Keep the investigation in the editor

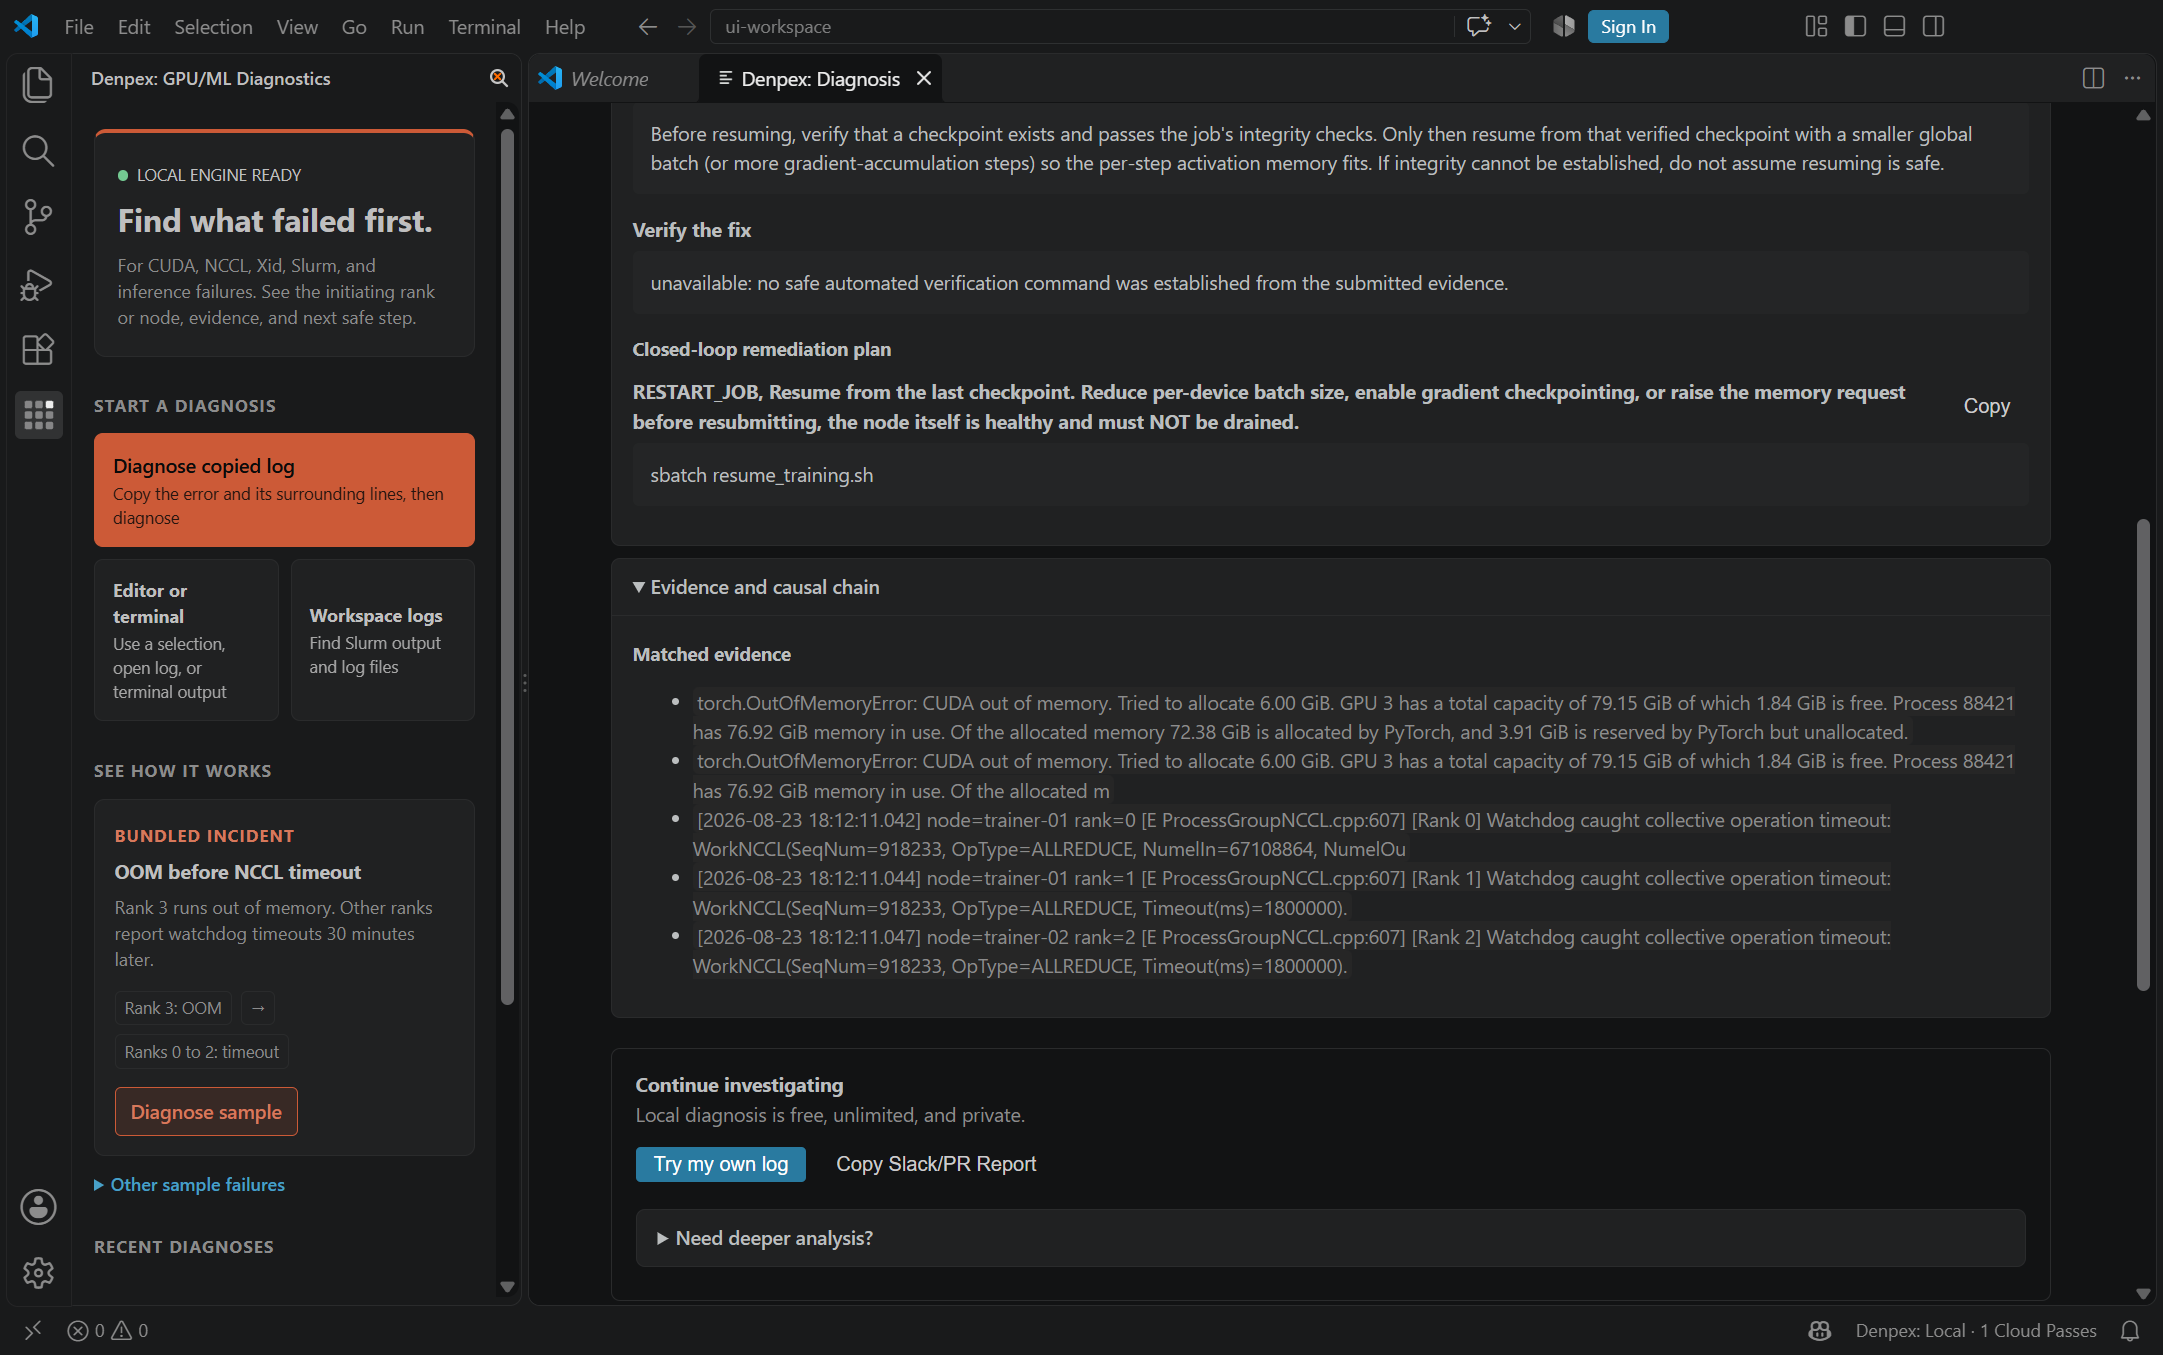
Denpex VS Code extension displaying a bundled OOM-before-NCCL example, matched log evidence, verification guidance and an investigation handoff.
Actual VS Code extension capture of the bundled OOM-before-NCCL example. Review matched log evidence, verification guidance and the investigation handoff without leaving the editor.Inspect original image
Failure Signature Triage

KT Cloud · NHN Cloud (한국 GPU 클러스터) - Observed Runtime Evidence

KT Cloud 공식 문서 확인

Incident pattern summary

멀티노드 분산 학습 중 3번 노드의 mlx5 포트 재시도 초과 에러로 인해 나머지 모든 정상 랭크가 AllReduce에서 멈출 때, 최초 발원 노드를 즉시 격리합니다.

Terminal traceback excerpt (KT Cloud · NHN Cloud (한국 GPU 클러스터))
kr-h100-03:2044:2091 [3] misc/ibvwrap.cc:284 NCCL WARN Call to ibv_poll_cq returned error 12 (Transport retry counter exceeded)
NVRM: Xid (PCI:0000:4b:00): 79, pid=18402, name=pt_main_thread, GPU has fallen off the bus.

Recommended verification flags

Set these environment flags in your training container or launch script to capture high-resolution collective logs:

NCCL_DEBUG=INFONCCL_IB_HCA=mlx5TORCH_NCCL_ASYNC_ERROR_HANDLING=1CUDA_DEVICE_ORDER=PCI_BUS_ID

Diagnostic Scope Boundary

Denpex는 업로드된 로그와 하드웨어 상태 파일만 분석하며 고객사 클라우드 제어 평면이나 VPC에 직접 접근하지 않습니다.

Other GPU Cloud Failure Workflows

Compare evidence patterns across multi-node fabrics, Kubernetes pods, and bare-metal environments.

RunPoden
Separate container socket misrouting from a true worker stall on RunPod.
Lambdaen
Distinguish an InfiniBand mlx5 fabric flap from an application rank stall on Lambda.
Vast.aien
Isolate motherboard PCIe P2P restrictions and /dev/shm limits on Vast.ai hosts.
Scalewayen
Separate RoCE v2 GID routing mismatches from DeepSpeed ZeRO-3 stage stalls on Scaleway.
CoreWeaveen
Link Kubernetes pod restarts directly to underlying Xid 79 or NVLink hardware faults.
Crusoe Clouden
Pinpoint which straggler rank or RoCE link slowed down your Crusoe Cloud cluster.
Hetzneren
Fix vSwitch MTU fragmentation and NCCL socket discovery on Hetzner bare metal.
TensorDocken
Untangle NAT port forwarding and c10d rendezvous timeouts on TensorDock VMs.
さくらインターネット 高火力ja
さくら高火力サービスにおけるH100 NDR/RoCE NCCLタイムアウトの自動診断
GPUSOROBAN (Highreso)ja
GPUSOROBANにおける多重GPU P2P通信ストールとPCIeトポロジ競合の解決
네이버 클라우드 플랫폼ko
네이버 클라우드 GPU 인스턴스 DDP 랑데부 멈춤 및 VPC MTU 병목 진단
TWCC (台灣智慧雲 / Taiwania)zh-TW
TWCC 台灣智慧雲 GPU 叢集 Xid 79 PCIe 掉卡與 Slurm 任務卡死自動診斷
Nebiusen
Isolate InfiniBand fabric drops and Soperator node faults on Nebius.
KakaoCloudko
KakaoCloud GPU 클러스터의 NCCL 타임아웃과 네트워크 병목 분리 진단
SMC (Sustainable Metal Cloud Singapore)en
Isolate InfiniBand NDR rail faults and multi-node NCCL stalls in Singapore.
Hyperstack (UK & Europe)en-GB
Separate UK VM network bottlenecks from H100 hardware drops on Hyperstack.
CUDO Compute (UK & Europe)en-GB
Untangle virtualized PCIe topology and /dev/shm traps on CUDO Compute.
OVHcloud (France & Europe)en
Isolate OVHcloud vRack VLAN fragmentation from GPU silicon faults.
Verne & Nordic H100 Clustersen
Separate Slurm cgroup evictions from InfiniBand stalls on Nordic clusters.
Core42 (UAE Sovereign AI Cloud)en
Pinpoint initiating silicon and InfiniBand faults in thousand-GPU runs.
Firmus & ResetData (Australia)en
Separate network topology timeouts from hardware Xids on Australian GPUs.
GMO GPUクラウド · ABCI 3.0 (H200)ja
H200 InfiniBand NDR 通信障害と Slurm 強制終了を瞬時に切り分け
Ubilink 友崴超算 (台灣與港澳 H100 叢集)zh-TW
精準隔離 Ubilink H100 多節點訓練中的鏈路異常與硬體掉卡