For australian enterprise ai, research, and inference platform teams
Separate network topology timeouts from hardware Xids on Australian GPUs.
Capture nvidia-smi thermal/ECC evidence, InfiniBand rail bindings, and vLLM engine crashes before rerunning workloads.
Free 30-day Team evaluation. No card or automatic subscription. Work email verification required.
Replay an Australian H100 multi-GPU cluster incident
Upload your log file. Review the selected evidence and masking, then run diagnosis. Keep the original log for any follow-up questions.
Before uploading, review cloud data handling and local options.
Upload your log file. Large files are processed in your browser. Only selected evidence is submitted when you run diagnosis.
Try Denpex for 30 days. FREE.
No credit card. No automatic subscription. See whether Denpex helps with an incident you already understand.
Start your free 30-day Team evaluation
Up to 50 diagnoses a day for 30 days. Verify your work email to activate an eligible company evaluation, then replay a resolved incident and compare the evidence and next steps with your team's confirmed cause.
What a useful evaluation should establish
Deliver reproducible fix steps and clean hardware tickets for Australian sovereign GPU operators.
Use Denpex alongside your existing telemetry tools to investigate submitted incident evidence. With monitoring configured on a supported plan, detected failures can trigger alerts and an automatic diagnosis from the captured evidence.
Inside Denpex
See the evidence, not just the claim
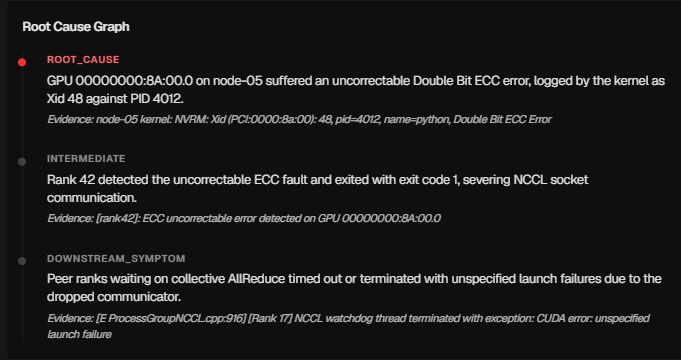
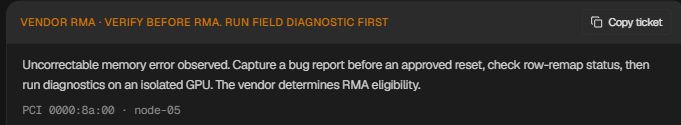
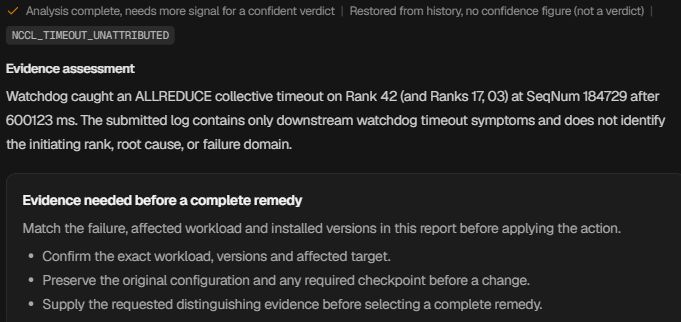
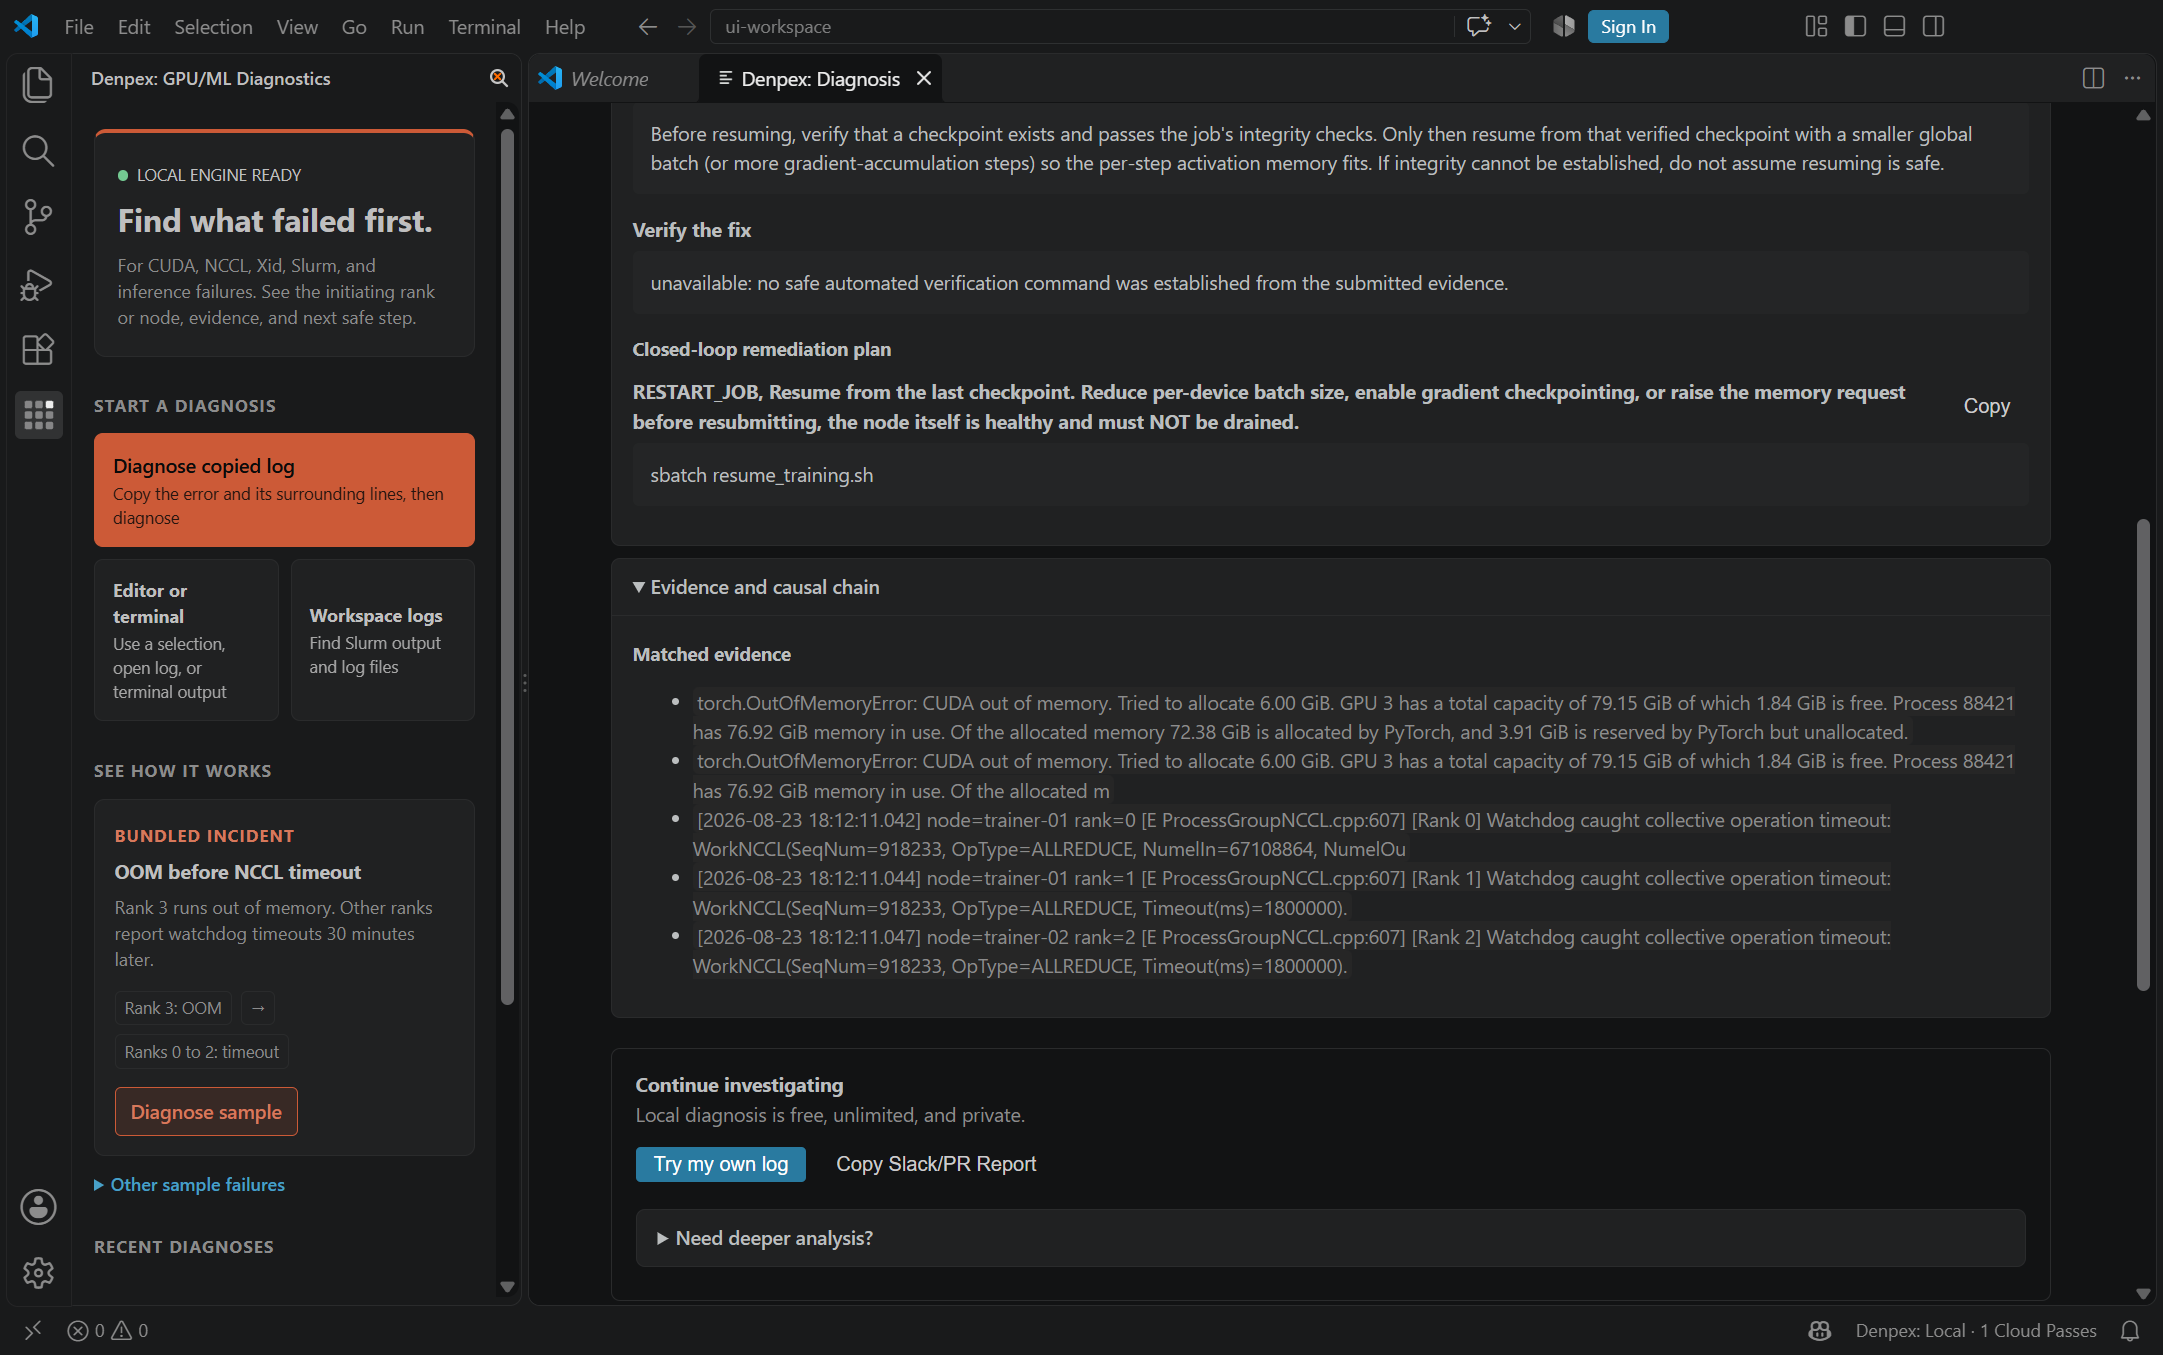
Follow the causal chain, inspect the quoted evidence and prepare the next handoff. These actual product captures use founder-account examples and the VS Code extension, with the source identified under each image. Open a capture to inspect it at full size.
Follow the failure through the cascade
Prepare the hardware escalation
Ask for the evidence that is missing
Keep the investigation in the editor
Firmus & ResetData (Australia) - Observed Runtime Evidence
Incident pattern summary
A Melbourne multi-node inference and fine-tuning job aborts mid-step with ProcessGroupNCCL timeout caused by a mismatched RoCE GID index on node 2.
au-h100-node02:1420:1455 [0] NCCL WARN NET/IB : Unable to query GID 3 on mlx5_0, falling back to socket transport
[E ProcessGroupNCCL.cpp:915] [Rank 8] Watchdog caught collective operation timeout: WorkNCCL(SeqNum=219, OpType=ALLREDUCE)
Recommended verification flags
Set these environment flags in your training container or launch script to capture high-resolution collective logs:
NCCL_DEBUG=INFONCCL_IB_HCA=mlx5NCCL_IB_GID_INDEX=3TORCH_NCCL_ASYNC_ERROR_HANDLING=1Diagnostic Scope Boundary
Denpex evaluates logs locally or via API and never requires inbound access to air-gapped sovereign networks.
Other GPU Cloud Failure Workflows
Compare evidence patterns across multi-node fabrics, Kubernetes pods, and bare-metal environments.