For 台灣人工智慧實驗室、半導體模型研發團隊及分散式訓練架構師
TWCC 台灣智慧雲 GPU 叢集 Xid 79 PCIe 掉卡與 Slurm 任務卡死自動診斷
精確區分 Slurm 節點被排程管理器取消、單卡散熱降頻導致的全叢集拖後腿,以及 PCIe 匯流排掉卡 (Xid 79) 硬體故障。
Free 30-day Team evaluation. No card or automatic subscription. Work email verification required.
重現 TWCC 台灣智慧雲 Slurm 訓練任務故障日誌
Upload your log file. Review the selected evidence and masking, then run diagnosis. Keep the original log for any follow-up questions.
Before uploading, review cloud data handling and local options.
Upload your log file. Large files are processed in your browser. Only selected evidence is submitted when you run diagnosis.
Try Denpex for 30 days. FREE.
No credit card. No automatic subscription. See whether Denpex helps with an incident you already understand.
Start your free 30-day Team evaluation
Up to 50 diagnoses a day for 30 days. Verify your work email to activate an eligible company evaluation, then replay a resolved incident and compare the evidence and next steps with your team's confirmed cause.
What a useful evaluation should establish
在數十個甚至數百個 GPU 的分散式集體逾時中,秒速鎖定唯一觸發崩潰的實體卡與主機節點,加快工單處理與復原流程。
Use Denpex alongside your existing telemetry tools to investigate submitted incident evidence. With monitoring configured on a supported plan, detected failures can trigger alerts and an automatic diagnosis from the captured evidence.
Inside Denpex
See the evidence, not just the claim
Follow the causal chain, inspect the quoted evidence and prepare the next handoff. These actual product captures use founder-account examples and the VS Code extension, with the source identified under each image. Open a capture to inspect it at full size.
Follow the failure through the cascade
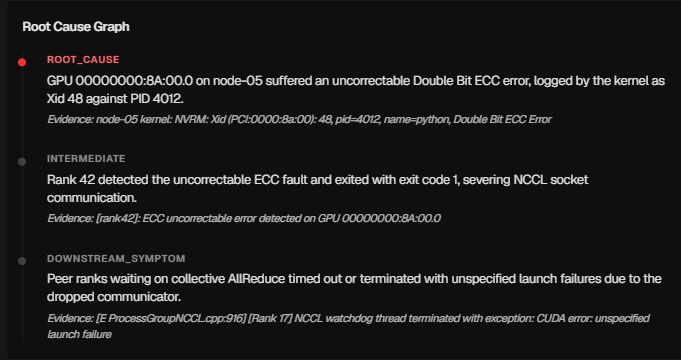
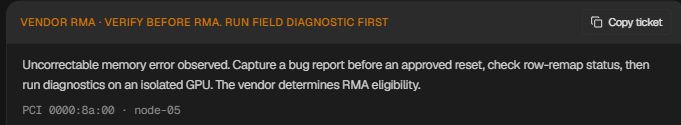
Prepare the hardware escalation
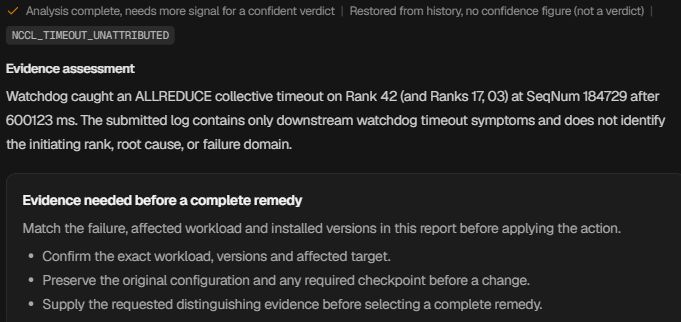
Ask for the evidence that is missing
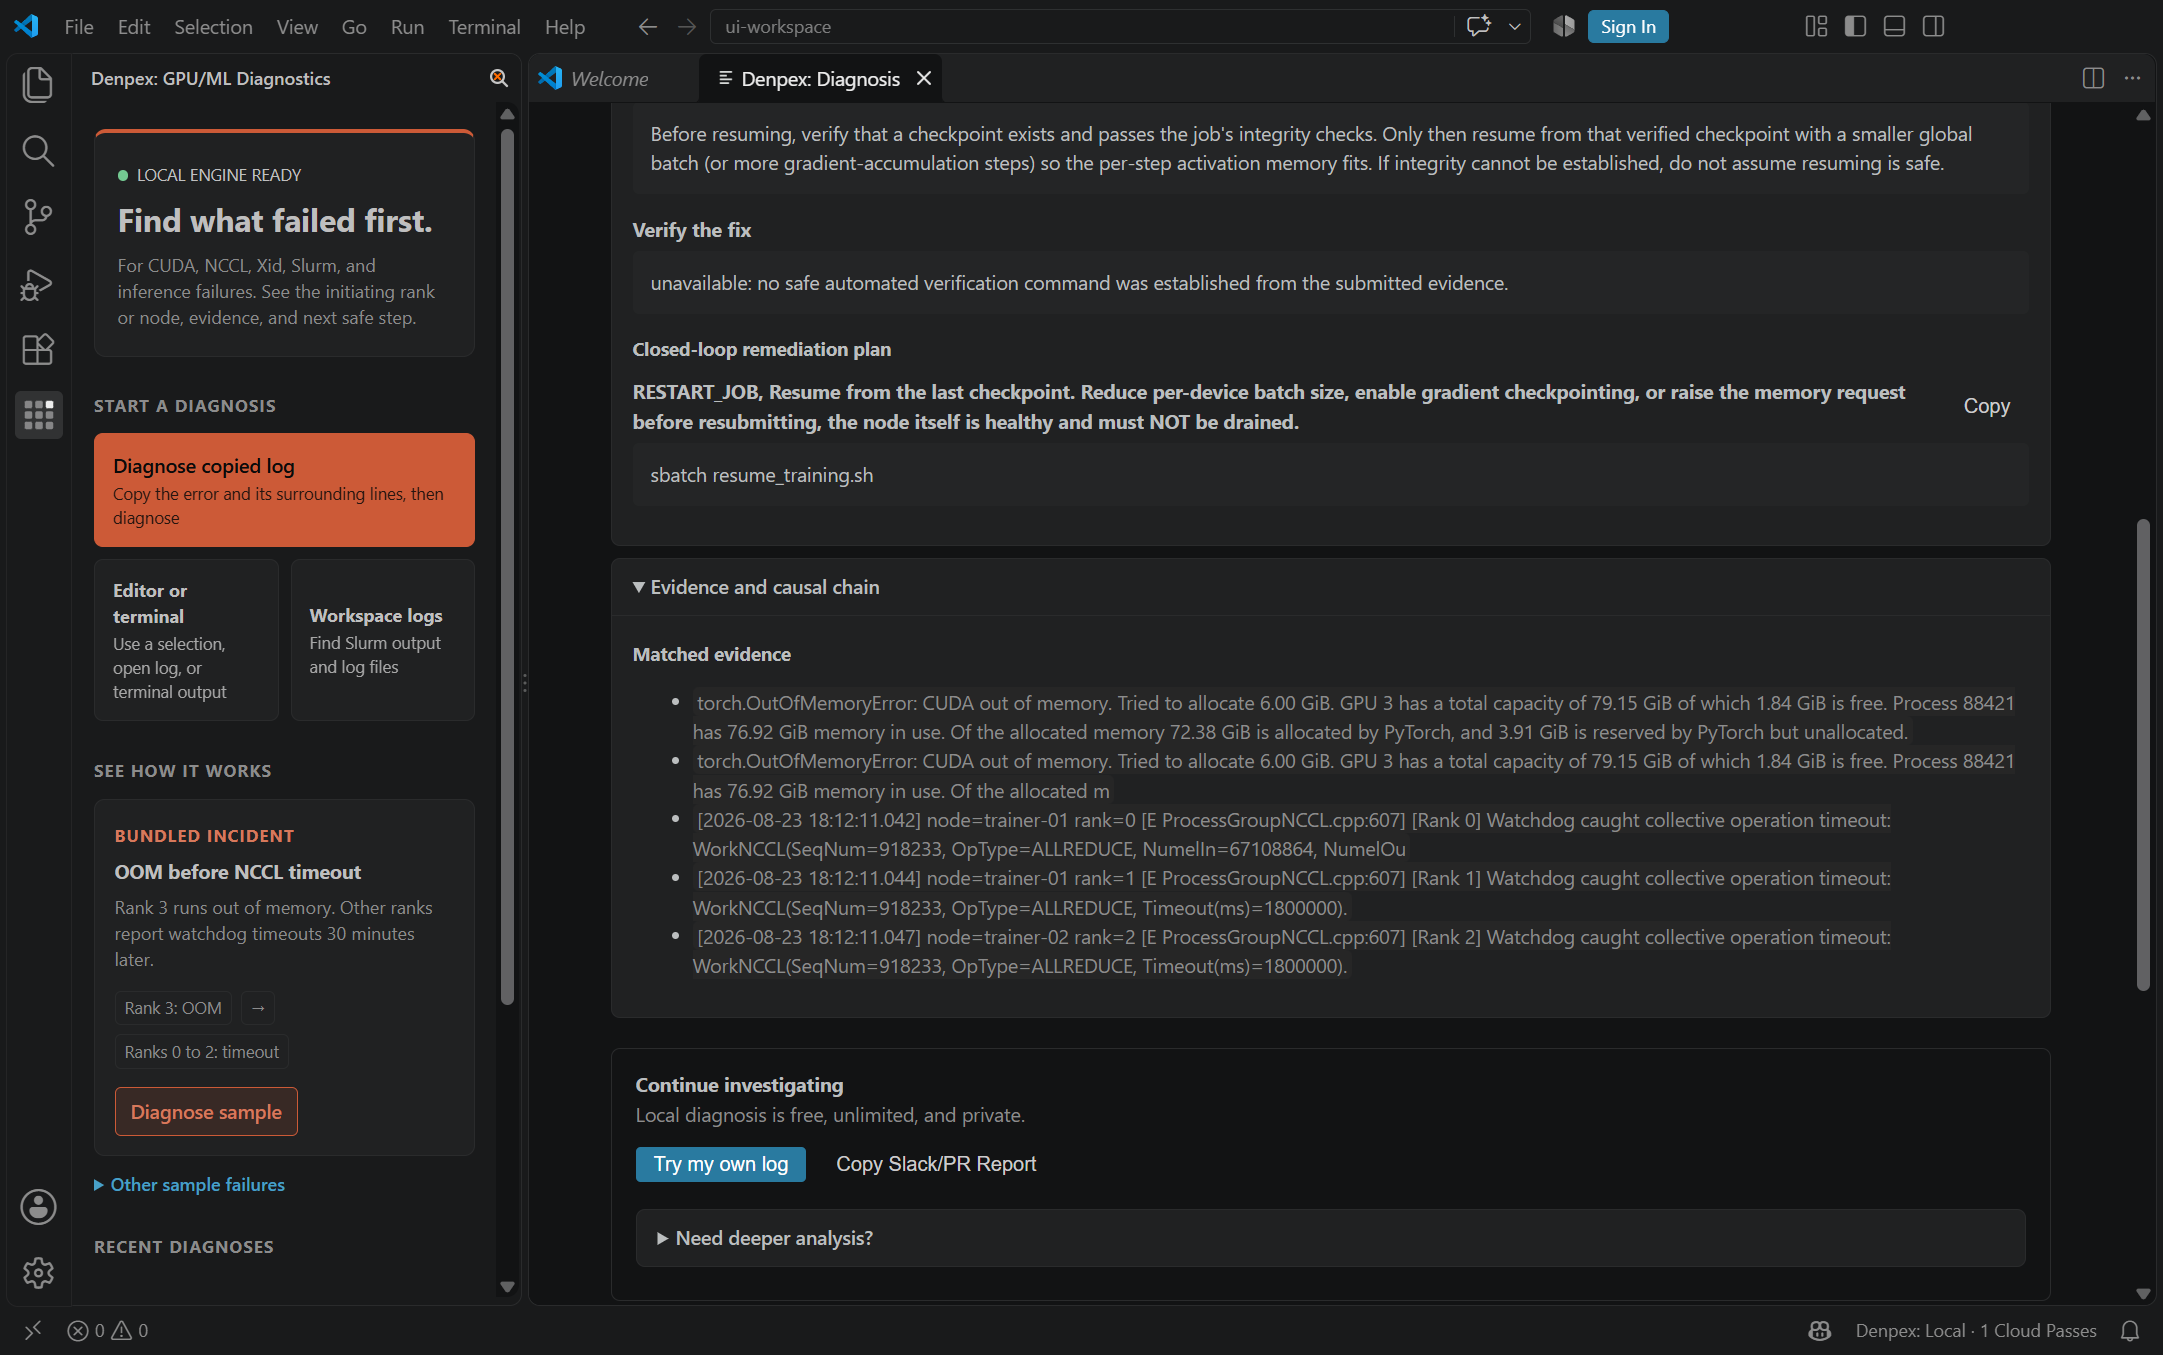
Keep the investigation in the editor
TWCC (台灣智慧雲 / Taiwania) - Observed Runtime Evidence
Incident pattern summary
在台灣杉超級電腦上執行多節點 FSDP 訓練任務時,因節點 4 的單一 GPU 掉卡 (Xid 79),導致其餘所有 GPU 在 all_reduce 屏障集體卡死。Denpex 於 14 毫秒內隔離出真正的故障節點,避免誤怪健康節點。
NVRM: GPU at PCI 0000:43:00.0: GPU has fallen off the bus.
NVRM: A GPU internal error has occurred. (Xid: 79)
slurmd[node04]: error: *** JOB 948211 ON node04 CANCELLED AT 2026-10-28T04:12:00 DUE TO TIME LIMIT ***
[E ProcessGroupNCCL.cpp:915] [Rank 0] Watchdog caught collective operation timeout: WorkNCCL(SeqNum=1284, OpType=ALLREDUCE, Timeout(ms)=600000)
Recommended verification flags
Set these environment flags in your training container or launch script to capture high-resolution collective logs:
NCCL_DEBUG=INFOTORCH_NCCL_ASYNC_ERROR_HANDLING=1CUDA_LAUNCH_BLOCKING=1TORCH_DISTRIBUTED_DEBUG=DETAILDiagnostic Scope Boundary
Denpex 無法直接修改 TWCC 的 Slurm 節點排程分區或重置實體硬體插槽。分析結果將提供具備完整數據佐證的故障報告,便於向 TWCC 維運團隊提交節點報修。
Other GPU Cloud Failure Workflows
Compare evidence patterns across multi-node fabrics, Kubernetes pods, and bare-metal environments.