For voltage park infrastructure and model engineering teams
Voltage Park Kubernetes: pod restart, input failure or GPU event?
Compare pod lifecycle with the first application exception and existing telemetry. Add a workload handoff alongside the platform monitoring already in place.
Free 30-day Team evaluation. No card or automatic subscription. Work email verification required.
Replay a resolved Voltage Park workflow incident
Upload your log file. Review the selected evidence and masking, then run diagnosis. Keep the original log for any follow-up questions.
Before uploading, review cloud data handling and local options.
Upload your log file. Large files are processed in your browser. Only selected evidence is submitted when you run diagnosis.
Try Denpex for 30 days. FREE.
No credit card. No automatic subscription. See whether Denpex helps with an incident you already understand.
Start your free 30-day Team evaluation
Up to 50 diagnoses a day for 30 days. Verify your work email to activate an eligible company evaluation, then replay a resolved incident and compare the evidence and next steps with your team's confirmed cause.
What a useful evaluation should establish
Compare one incident your team has already resolved with the first failure, quoted evidence and remaining questions. Begin with this question: What ended the affected container? Only assign a process, device or recovery state when the submitted evidence establishes it.
What ended the affected container?
Evidence to compare: Pod termination reason, restart sequence and retained worker output.
A restarted pod can hide an earlier process error. Review the first failed attempt and its resource context before treating a fresh container as a new incident.
Did the data path precede the collective failure?
Evidence to compare: Input-reader exceptions, storage events and timestamped worker progress.
Use the actual mount and storage evidence. A known storage product alone does not prove a storage fault or justify changing the whole platform.
What did platform recovery actually restore?
Evidence to compare: Control-plane recovery events and separately verified workload artifacts.
Restoring cluster state and recovering training progress are different operations. Check model artifacts and job state independently before recommending resume.
Use Denpex alongside your existing telemetry tools to investigate submitted incident evidence. With monitoring configured on a supported plan, detected failures can trigger alerts and an automatic diagnosis from the captured evidence.
Inside Denpex
See the evidence, not just the claim
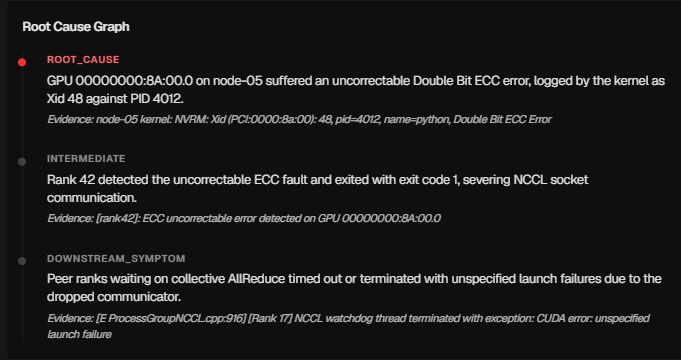
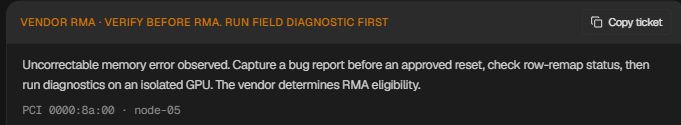
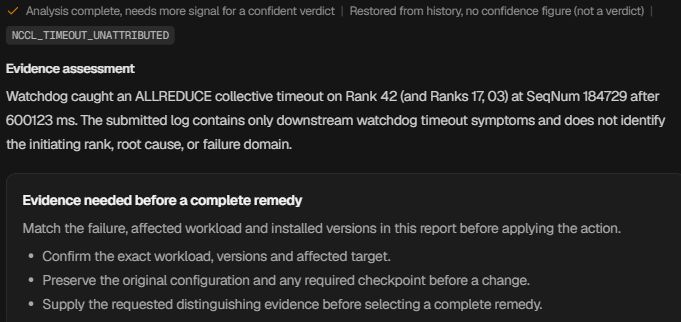
Follow the causal chain, inspect the quoted evidence and prepare the next handoff. These actual product captures use founder-account examples and the VS Code extension, with the source identified under each image. Open a capture to inspect it at full size.
Follow the failure through the cascade
Prepare the hardware escalation
Ask for the evidence that is missing
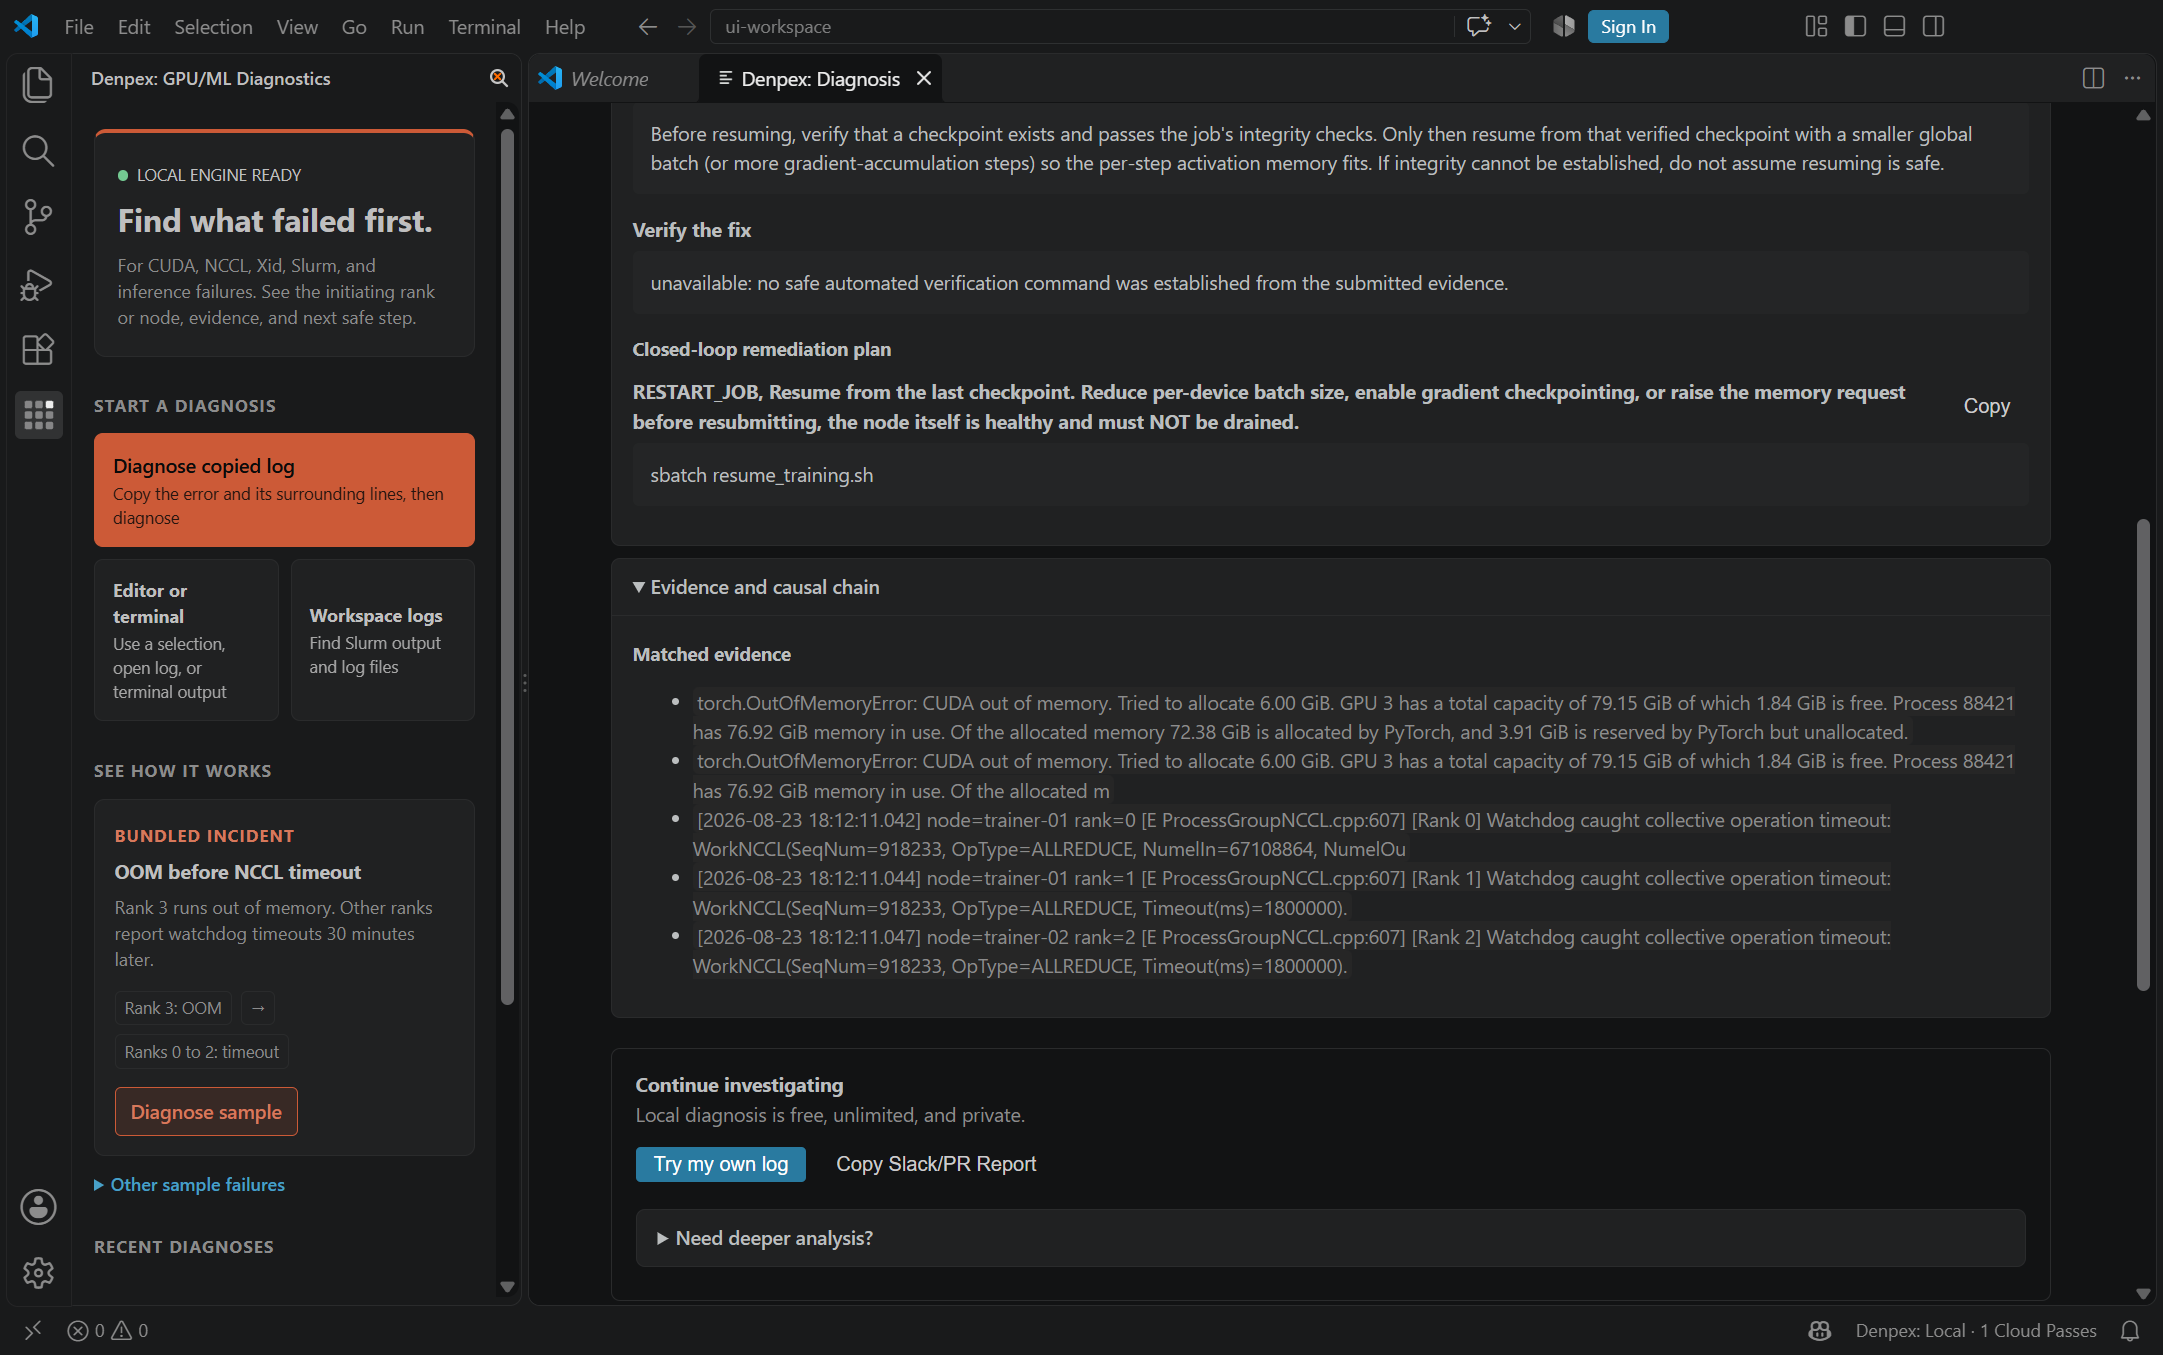
Keep the investigation in the editor