For liquid ai infrastructure and model engineering teams
LFM2 failed to load: backend compatibility or device memory?
Identify the runtime and actual device before comparing the first loading error. Separate unsupported model code from a later serving or allocation failure.
Free 30-day Team evaluation. No card or automatic subscription. Work email verification required.
Replay a resolved Liquid AI workflow incident
Upload your log file. Review the selected evidence and masking, then run diagnosis. Keep the original log for any follow-up questions.
Before uploading, review cloud data handling and local options.
Upload your log file. Large files are processed in your browser. Only selected evidence is submitted when you run diagnosis.
Try Denpex for 30 days. FREE.
No credit card. No automatic subscription. See whether Denpex helps with an incident you already understand.
Start your free 30-day Team evaluation
Up to 50 diagnoses a day for 30 days. Verify your work email to activate an eligible company evaluation, then replay a resolved incident and compare the evidence and next steps with your team's confirmed cause.
What a useful evaluation should establish
Compare one incident your team has already resolved with the first failure, quoted evidence and remaining questions. Begin with this question: Which LFM2 runtime and device were selected? Only assign a process, device or recovery state when the submitted evidence establishes it.
Which LFM2 runtime and device were selected?
Evidence to compare: Model revision, backend version and actual CPU or GPU target.
The model has several deployment paths. Preserve that choice so a CPU compatibility issue does not receive CUDA-only remediation.
Did the loader recognize the model implementation?
Evidence to compare: The first model-type or import exception and package versions.
An unsupported architecture can prevent weight initialization. Compare release compatibility before changing memory settings or blaming the device.
Did a serving worker fail after successful loading?
Evidence to compare: Readiness event, first request failure and worker termination reason.
Separate loading success from request execution. A downstream API error needs its worker timeline before any inference about cache or concurrency limits.
Use Denpex alongside your existing telemetry tools to investigate submitted incident evidence. With monitoring configured on a supported plan, detected failures can trigger alerts and an automatic diagnosis from the captured evidence.
Inside Denpex
See the evidence, not just the claim
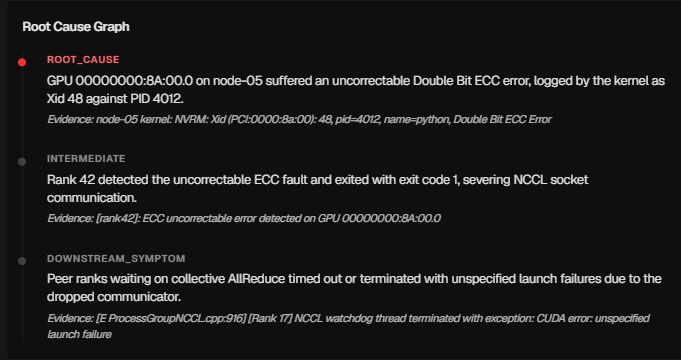
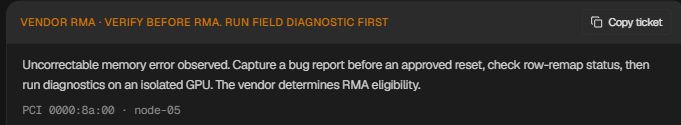
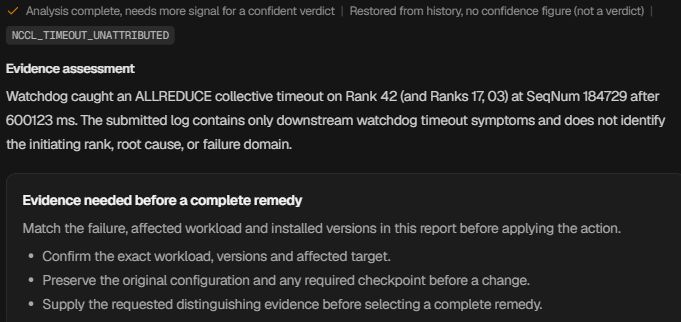
Follow the causal chain, inspect the quoted evidence and prepare the next handoff. These actual product captures use founder-account examples and the VS Code extension, with the source identified under each image. Open a capture to inspect it at full size.
Follow the failure through the cascade
Prepare the hardware escalation
Ask for the evidence that is missing
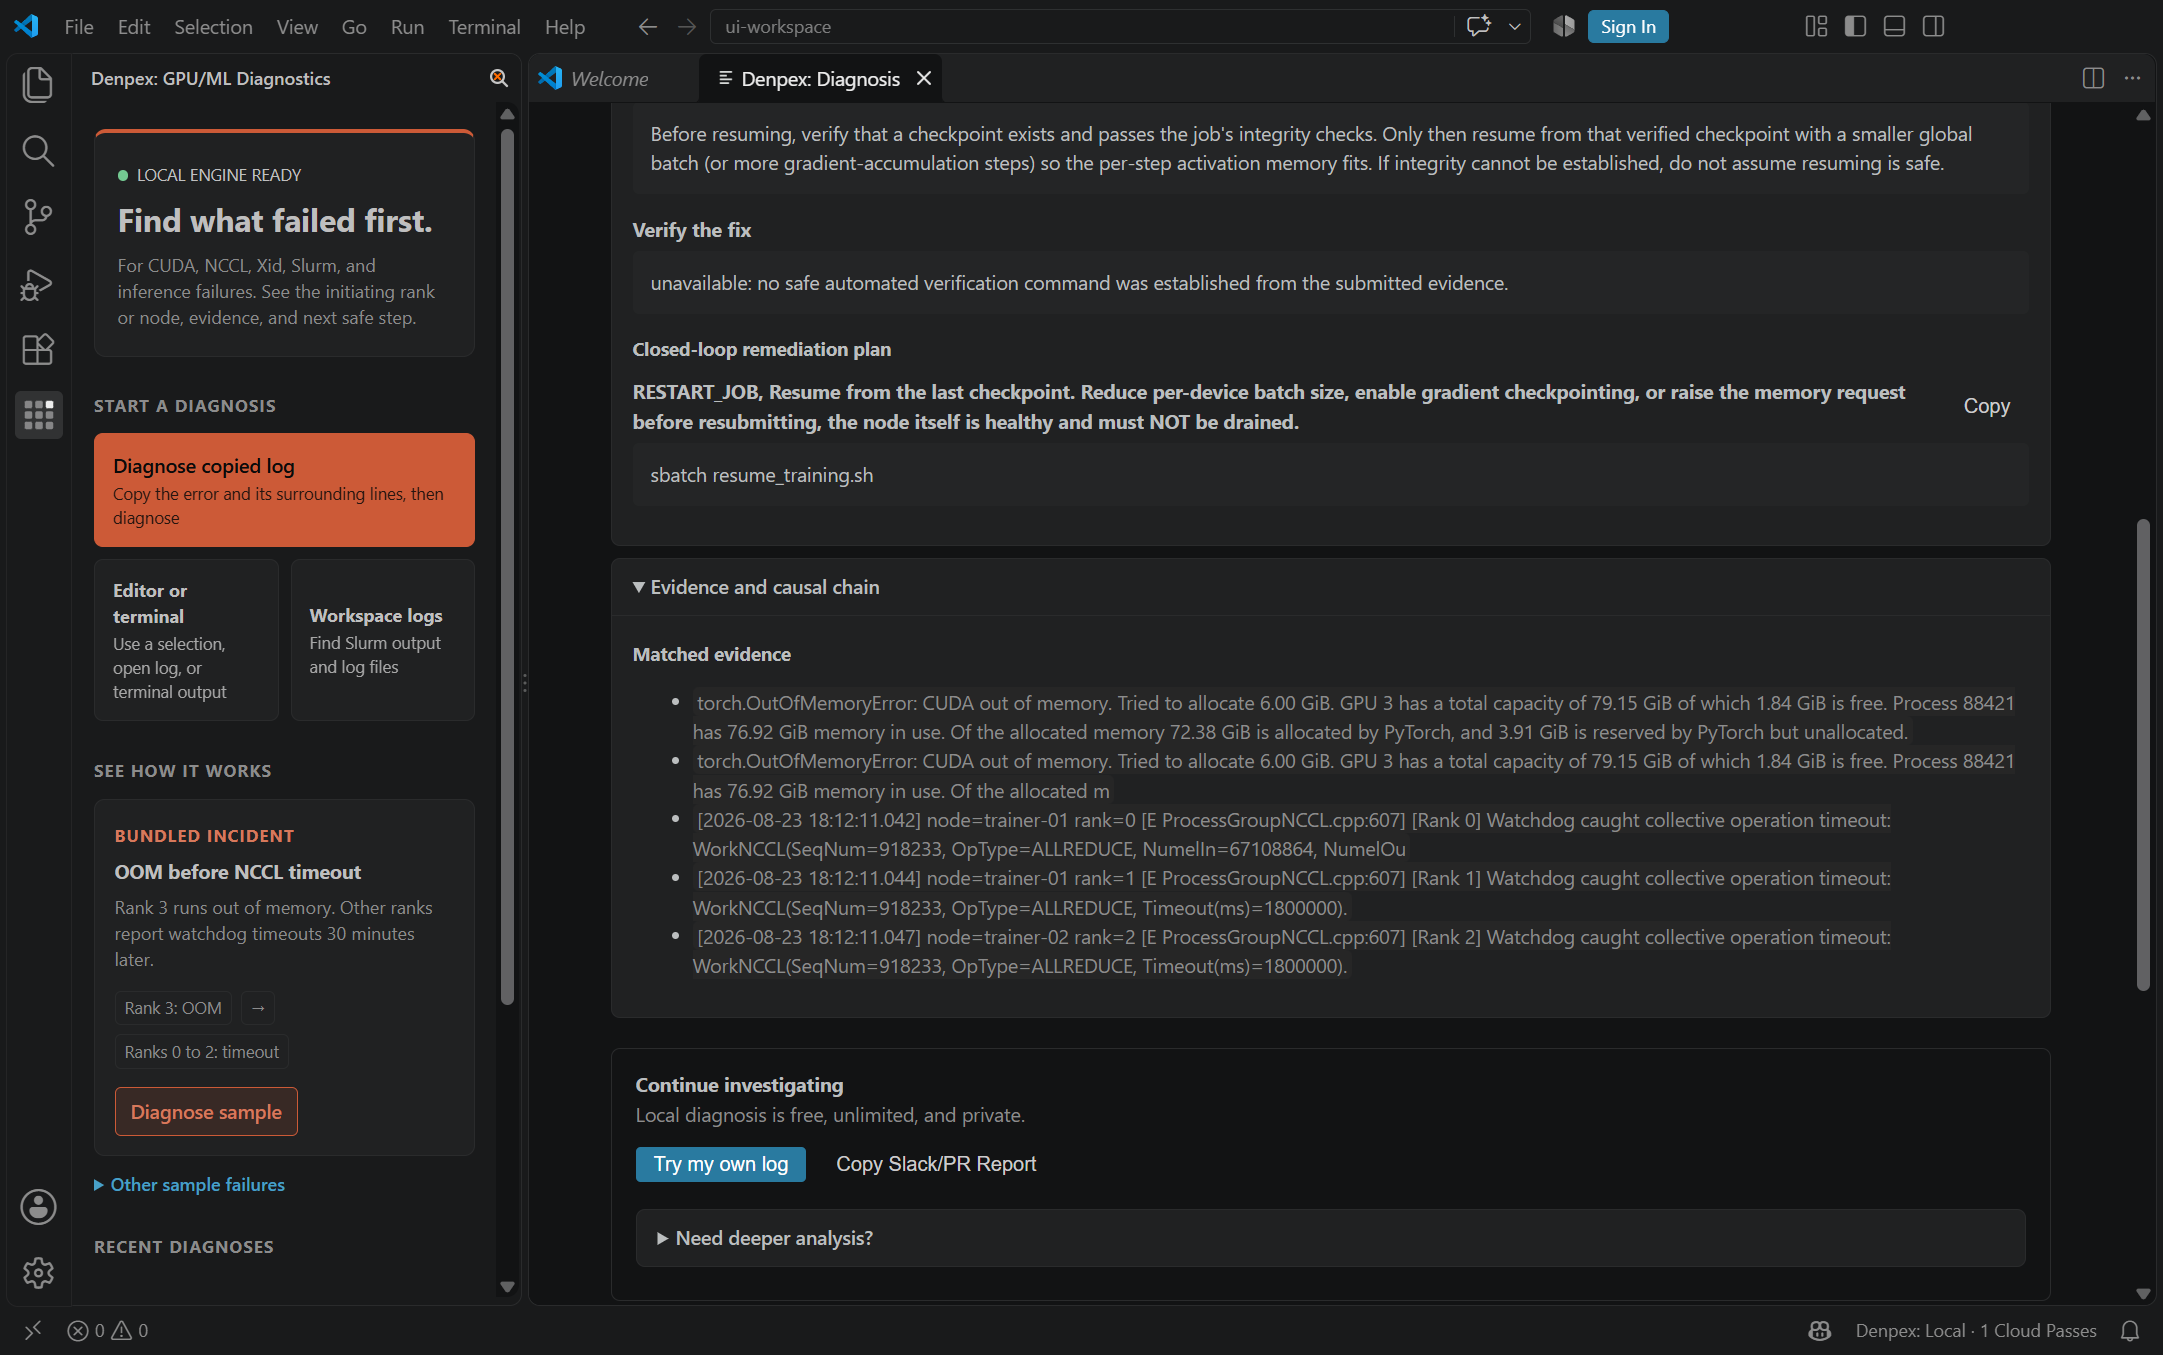
Keep the investigation in the editor